Rapid RNA sequencing for precision oncology
A precision oncology centre needed an end-to-end pipeline to analyse NanoString nCounter data and produce physician-ready reports within minutes, for individual cancer samples without paired normal controls.
The challenge
A precision oncology centre needed a complete genomic analysis solution to support real-time clinical decisions for cancer patients, with a workflow that processes NanoString nCounter data and generates physician-ready reports within minutes. The technical difficulties were analysing individual cancer samples without paired normal controls, maintaining statistical rigour, processing large datasets efficiently, and giving clinicians actionable treatment recommendations at the point of care.
What we set out to do
- Build a complete RNA sequencing analysis pipeline for NanoString nCounter data
- Enable single-sample differential expression analysis without paired controls
- Reach sub-minute processing times for clinical datasets
- Create an integrated PDF report generation system for physicians
- Scale to processing 1,500+ samples per month
- Implement comprehensive quality control and normalisation modules
Our approach
Data architecture analysis
Evaluated the structure of NanoString nCounter data, curated publicly available PBMC reference datasets for comparison, modified reference data for kit version compatibility, and established a method for comparing samples against healthy blood-based samples.
Technical implementation
Integrated the NanoTube Bioconductor package for core analysis, developed a single-sample differential expression method, implemented QC modules with RUV and nSolver as backup methods, and built a multi-criteria gene ranking algorithm using fold-change, p-value, abundance, and coefficient of variation.
Modular, reproducible build
Created a modular architecture for future enhancements, wrote an automated installation script for all dependencies, and set up version control through a GitHub repository.
Solution delivery
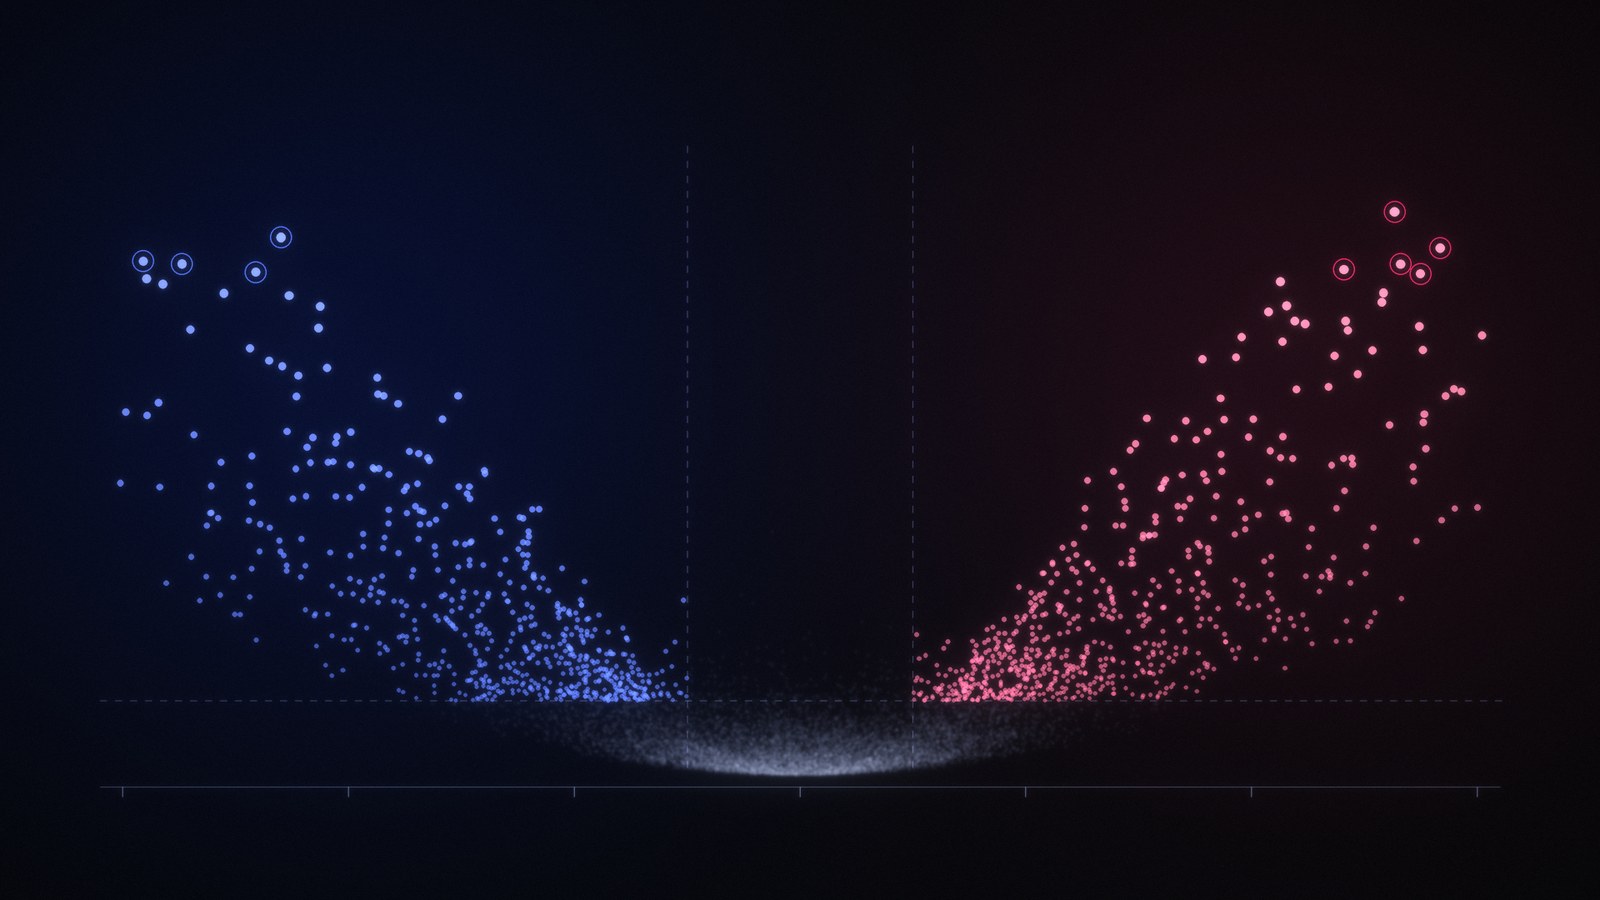
Built a PDF report generation system with dynamic data integration, created a visual analytics framework for gene expression significance, provided a template framework with structured patient data, and delivered documented execution scripts with usage instructions.
Results and impact
The pipeline delivered sub-minute processing for datasets exceeding 3,800 samples, with scalability validated for 1,500+ samples per month. It was delivered ahead of the original four-week timeline (completed in under three weeks) and successfully processed actual client-provided datasets during validation. A reference database with healthy population controls was built, enabling real-time clinical decision support and physician-ready reports with actionable treatment insights.
“Umbizo delivered a complete, production-ready solution that processes our genomic data in real time. The single-sample analysis approach and sub-minute processing time let our team bring genomic insights directly into patient consultations.”
Timeline
- Requirements analysis and design: 3 days
- Core pipeline development and integration: 1 week
- Report generation system development: 4 days
- Testing and validation: 3 days
- Total: under 3 weeks (ahead of the 4-week target)
Looking forward
Expanding the drug treatment database with cytotoxic versus immuno-stimulatory classifications, and adding further reference populations to strengthen comparisons across diverse patient demographics.